Reflection Opens Beam, Argon Agents Slay the Dragon & Claude Reviews Its Own Code
Dispatches of the past four-and-twenty hours from the laboratories of artificial intelligence
Open Weights
Reflection Opens Beam, Its First Model
501B total / 23B active under Apache 2.0—#2 among U.S. open weights, and free on Ollama for now
By Our Open-Weights Desk
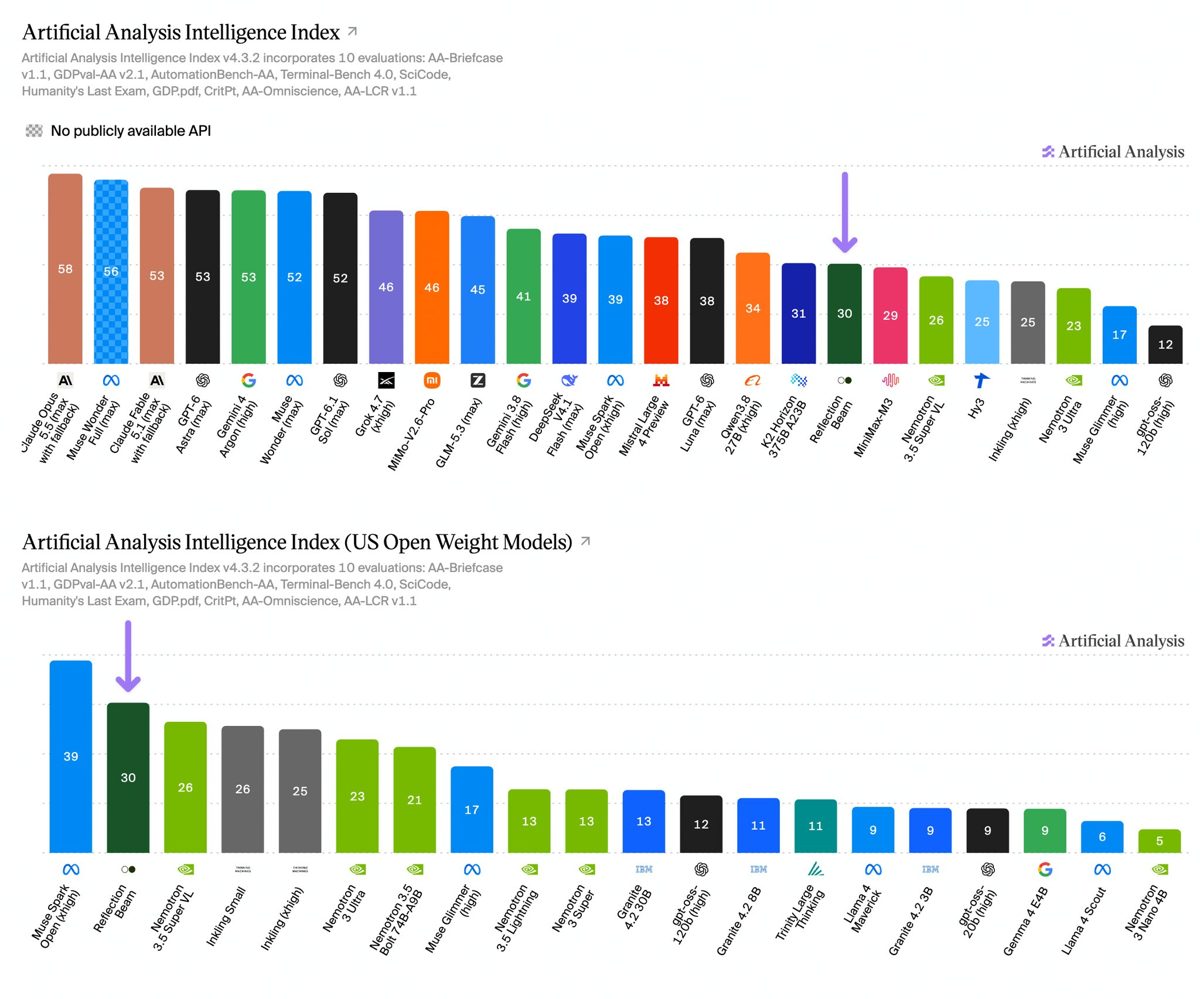
Artificial Analysis Intelligence Index: Beam scores 30, second among U.S. open-weights models behind Muse Spark Open (39).מדד ה־Intelligence של Artificial Analysis: Beam מקבל 30, שני בין המודלים הפתוחים בארה״ב אחרי Muse Spark Open (39).Image: תמונה: @ArtificialAnlys on X
Reflection AI released its first open-weight model on Friday, and it did not arrive alone. Beam ships under the Apache 2.0 license with weights, tokenizer and a reference implementation; BF16, FP8 and NVFP4 builds; a DFlash2 drafter; and Mirror CLI, the open-source harness Reflection trained it on. More than forty partners lined up for day one.
Artificial Analysis scored it 30 on its Intelligence Index: second among U.S. open-weights models, behind only Meta’s Muse Spark Open (39). It has 501B parameters in total and 23B active, a 1M-token context, and reads text only. Its party trick is thrift: about 26k output tokens per index task, half of what the UAE’s K2 Horizon spends for one point more. It also leads U.S. open models on the Cyber Index, at 34%.
Not every number flatters. Beam managed just 3.0% on Terminal-Bench 4.0, and on AA-Omniscience it hallucinates 47% of the time even while answering 33% correctly. Ollama, meanwhile, made it free for a limited time on its U.S.-hosted cloud with zero data retention: ollama run beam, or launch it inside Claude Code, Codex or OpenCode.
Several agents per task in ChatGPT’s Chat tab—and Codex stretches your usage with smarter caching
By Our San Francisco Desk
OpenAI upgraded GPT-6 Astra Pro in ChatGPT: faster answers, better use of plugins and tools and, the headline, multiple agents that tackle different parts of one task in parallel. You can follow each agent’s progress and open finished pieces to review them. It is live for Pro users in the Chat tab.
Tibo’s public diary reached Day 12 with a quieter gift: Codex and Work now go further on the same plan, thanks to context reused across subagents, longer caching and routing that lands more cache hits. He adds that GPT-6 Pro improved for all Pro users. On the API side, 6-Astra Ultrafast joined the Agents API, sandbox snapshots bring idle environments back with files intact, and idle environments no longer bill.
27 hours, 2,783 self-written programs, no human help—while Argon spreads to AI Studio, Canvas and Perplexity
From the Mountain View Wire
Google DeepMind turned four Gemini 4 Argon agents loose in one shared Minecraft world with a single goal: defeat the Ender Dragon. Working in a sandbox through code and text only, they wrote 2,783 programs, split up jobs over chat, shared notes and debugged errors together. Twenty-seven hours in, with no human help, the dragon fell.
The model kept spreading. Google AI Pro subscribers can now build with Argon in AI Studio’s Build and Playground. The Gemini app’s Canvas turns dense PDFs into interactive, animated web apps. Perplexity opened Argon to all its users, citing a new state of the art on its Wide-And-Deep-Research benchmark. And Antigravity reset Argon and Gemini quotas for everyone, so people can keep building through the weekend.
Claude Writes 90% of Claude Code. Here’s Who Checks It.
Merged PRs more than doubled while reverts fell 40%—and Claude Code now starts answering up to 3× sooner
From the Claude Desk
Anthropic published how the Claude Code team reviews code when an agent writes most of it. From June to September, merged pull requests more than doubled while the share that had to be reverted fell by more than 40%. Across Anthropic’s monorepo, changes landing per day went from about 2,500 in May to more than 30,000 in September.
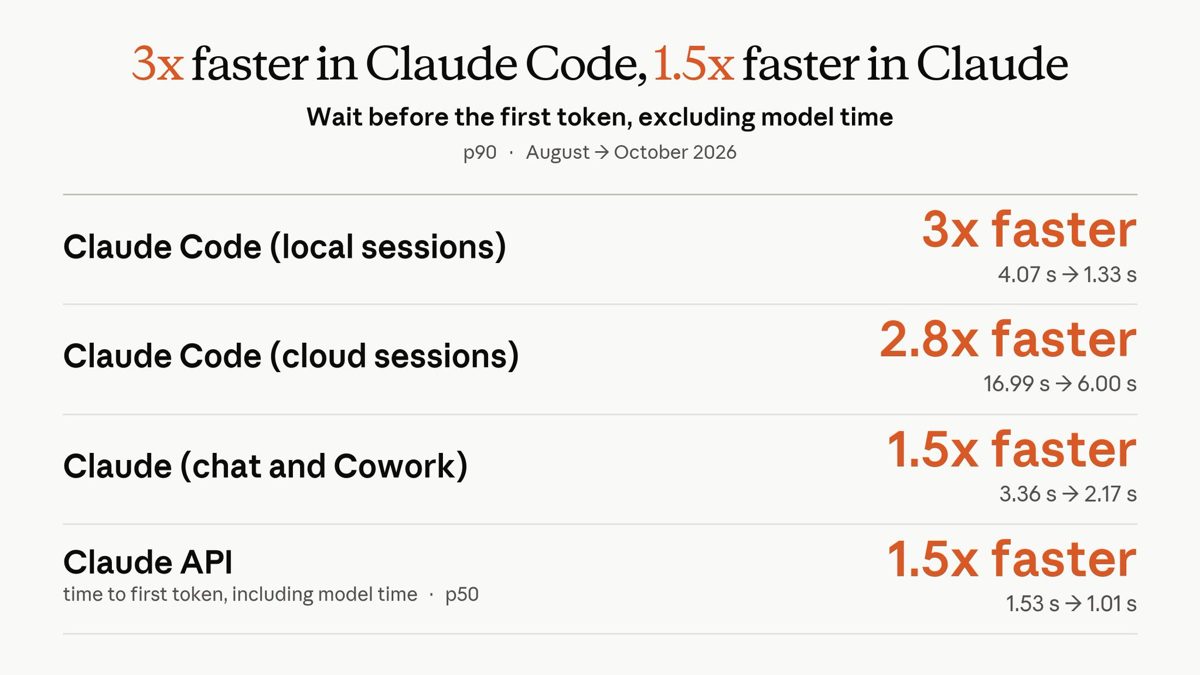
The trick is layers, not one gate: Claude verifies its own work, an AI reviewer reads every PR, other agents vote on each finding before it is posted, security review can block, and a classifier sets how many humans must approve. Separately, Claude Code now gzips the conversation it sends each turn, and cloud sessions start up while you type.
Wait before the first token (p90), August to October: 3× faster in local Claude Code sessions, 2.8× in cloud sessions, 1.5× in Claude chat and the API.המתנה עד הטוקן הראשון (p90), אוגוסט עד אוקטובר: פי 3 מהר יותר בסשנים מקומיים של Claude Code, פי 2.8 בסשנים בענן ופי 1.5 בצ׳אט וב־API.Image: תמונה: @ClaudeDevs on XDecision Models
Liquid’s d1-ultra Tops the Decision Index
A score of 65, earned by saying “I don’t know” 85% of the time it should
Benchmarks Bureau
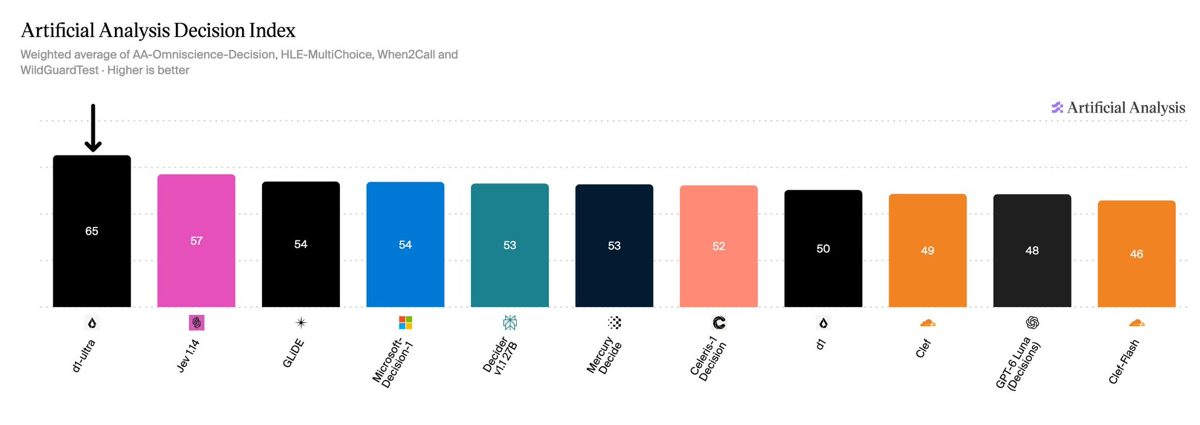
Liquid AI’s new d1-ultra took first place on the Artificial Analysis Decision Index with 65, ahead of Jev 1.14 (57) and of GLiDE and Microsoft-Decision-1 (54). The jump comes from humility: its non-hallucination rate on AA-Omniscience-Decision is 85%, up from 2% for d1. The cost is accuracy, down nine points to 32%. A task takes about 92 ms and costs $32 per million tasks, billed on input tokens only.
Artificial Analysis Decision Index: d1-ultra at 65, ahead of Jev 1.14 at 57.מדד ההחלטות של Artificial Analysis: d1-ultra עם 65, לפני Jev 1.14 עם 57.Image: תמונה: @ArtificialAnlys on XQuantum
Claude Mythos 5 Draws Better Quantum Circuits
From plain-language instructions, designs that beat the best published ones—sometimes by an order of magnitude
Science Desk
Anthropic’s STEM Fellows Program reports that Claude Mythos 5, given instructions in plain language, designed quantum circuits that improve on the best published ones, sometimes by an order of magnitude or more. The goal is more efficient circuits: the same computation with less work for the quantum hardware.
OpenClaw and Hermes Agent set up from Windows, no terminal required
Hardware Beat
NVIDIA’s RTX Spark laptops had their launch day across six cities, from Seoul, Taipei and Beijing to Berlin, Istanbul and San Francisco. Two open agents rode along. OpenClaw now sets up out of the box: pick a local model or a cloud provider and follow a guided setup without opening a terminal, work done with NVIDIA and Microsoft. Nous Research’s Hermes Agent is a launch partner too, selectable in the built-in Windows agent setup flow with a new generative onboarding.
Alexandr Wang: “We Have Built a Machine That Builds New Models”
A year into Meta Superintelligence Labs, a thank-you note for reaching the frontier—with no deadlines
From Menlo Park
After a week of launches, Muse Wonder (full) and Muse Spark Open, Alexandr Wang thanked the research teams at Meta Superintelligence Labs. MSL and TBD began a little over a year ago with a goal of a frontier model within about a year; given where Llama 4 landed, he calls it audacious, and says many told them it was impossible. Paradoxically, TBD ran on a principle of no deadlines. His proudest claim: beyond the models, the team built a scalable system to keep advancing at the frontier.
Jalapeño at TIME, Copilot Notebooks & a Navier-Stokes Shirt
OpenAI’s chip honored; Office editing in Notebooks; Mistral on STEMBench; HeyGen Video 1 lands in MCP
Roundup from the Wire
OpenAI’s first AI-acceleration chip, Jalapeño, made TIME’s Best Inventions of 2026 list. Nous Research, for its part, clarified that a post implying Hermes had made the list was satire by its social intern. Microsoft’s Copilot Notebooks can now delegate simple work to Copilot, build interactive reports and edit Word, Excel and PowerPoint files directly.
Mistral says Mistral Large 4 scores well in engineering and astronomy on Ulam’s private STEMBench. HeyGen Video 1, which HeyGen says is #1 on OpenRouter’s video leaderboard, is now in HeyGen MCP. ChatGPT’s dot became an iOS home-screen widget. Grok Bot redesigned its chat cards. And Sam Altman showed off the Navier-Stokes milestone shirt, whose back carries the last line of the solution’s chain of thought.
Wren & Robin read you this morning's dispatches, with banter.
Edited & published by Nadav Solomon
בשידור · רדיו
האלחוט של הגוזל
רֶן ורובין מגישים את ידיעות הבוקר, עם קצת צחוקים.
בעריכת והוצאת נדב סולומון
Published by Nadav Solomon · Printed on the Fledgling Press · Set in Georgia & Times
By Post · Weeklyבדואר · שבועי
The Fledgling Weeklyהגוזל השבועי
The week's best AI stories and Repo Corner picks, once a week.מיטב ידיעות ה-AI של השבוע ובחירות פינת הריפו, פעם בשבוע.
Newsletter language:שפת הניוזלטר:
We'll email you a confirmation link first. Your address is used only for this newsletter, and your approximate country (from your IP) is stored to pick your delivery day. Never shared; every issue has a one-click unsubscribe.קודם נשלח לך קישור לאישור. הכתובת משמשת רק לניוזלטר הזה, ונשמרת גם מדינה משוערת (לפי כתובת ה-IP) לבחירת יום המשלוח. לא מועבר לאף אחד, ובכל גיליון יש הסרה בלחיצה אחת.
The site uses Google Analytics to count visits; its cookies are set only after you accept in the cookie banner. Privacy policy.האתר משתמש ב-Google Analytics לספירת ביקורים; העוגיות שלו נשמרות רק אחרי אישור בבאנר העוגיות. מדיניות פרטיות.