Claude Stops Resending, Anthropic Eyes Self-Building AI & OpenAI Rebuilds Git
Dispatches of the past four-and-twenty hours from the laboratories of artificial intelligence
Anthropic · Claude API
Claude Stops Making Agents Resend the Whole Conversation
Message threads keep the chat on Anthropic’s side, so long sessions start answering about a third sooner
By Our Correspondent on the Wire
Anthropic put message threads into public beta on the Claude Messages API on Monday. Until now, an agent had to send the entire conversation, every earlier message and tool result, with each new request. With threads, the first request opens a thread and later ones send only what is new, plus the ID of the previous response.
The company already switched it on for most Claude Code users. On requests of 500,000 to a million tokens, the median wait for the first token fell by about 35 per cent, and in long conversations the median request shrank from about 800 KB to 1.8 KB.
The price does not change. Claude still reads the full conversation every turn, so token use stays the same; what you save is upload time. Threads work on the Claude Platform, on AWS, in Microsoft Foundry and on Google Cloud, at standard rates, with a thread parameter and a beta header.
Anthropic Tells Investors That AI Building AI May Be Close
A new line in its revised IPO filing says it may “imminently” meet its own bar for dramatically accelerated progress
By Our Correspondent in the Fine Print
Anthropic’s amended S-1, the filing for its planned stock-market listing, added new risk factors on Monday. One says that internal estimates about future models, not current ones, indicate the company “may imminently meet” its Responsible Scaling Policy’s definition of “dramatically accelerated progress attributable to AI.”
It also admits that, using AI in its own research, it has in the past not noticed a big jump in its pace of development until after it happened. No current model has been designated as over the line, and Anthropic writes that it does not expect to let Claude fully design the next generations of frontier models without meaningful human supervision.
On a lighter note, applications opened for the Anthropic Residency, a paid, fixed-term research programme for academics, technical founders and staff-level engineers. No machine-learning background is needed; the deadline is 22 November.
OpenAI Built Its Own Git Engine Because the Agents Kept Pushing
Pando cut push times by about 80 per cent and moves nearly a petabyte of code history a day
By Our Correspondent at the Repository
OpenAI revealed Pando, a new back end for the Git repository that holds most of its code. Engineers and coding agents use Git exactly as before, but pushes now take about 80 per cent less time, and Pando serves nearly a petabyte of Git data a day. OpenAI says it can now grow capacity alongside agent usage.
The trick: pushes to different branches are applied in parallel, while pushes to the same branch are still put in order. On a fetch, Pando hands the client links to stored bundles of objects, which may contain a little extra but can be reused by many readers at once. OpenAI also sent fixes back to Git itself, such as cleaning up after an interrupted download.
Codex chief Thibault Sottiaux summed it up: “We know some Git-fu.”
A Data Scientist in Every Pocket, Courtesy of a Team Bot
SpaceXSI’s Data Bot did an estimated 70 hours of analysts’ work last week, and a new video tours this month’s features
By Our Correspondent at the Dashboard
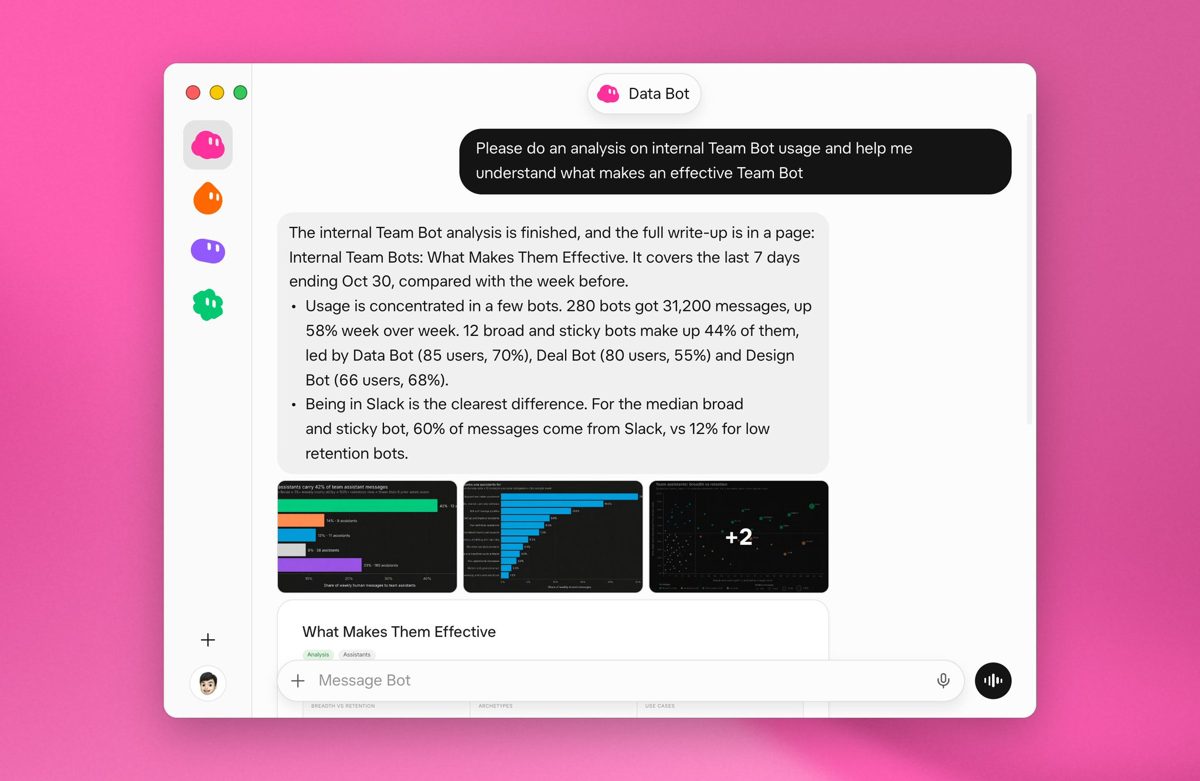
The Grok Bot team described Data Bot, a Team Bot that the company’s data scientists teach through shared skills. Product managers ask it about product usage, marketers ask whether a campaign actually changed behaviour, and teams have it build dashboards. Last week, the team estimates, it handled about 70 hours of work that would otherwise have landed on them.
Its memory is shared too, but managers approve each new fact before everyone gets it, such as a past drop in a metric that turned out to be a regional holiday. It can also sit in Slack channels and post weekly metric updates on its own.
A new “What’s New in Grok Bot” video from @mattyp walks through shopping cards, product pages, order tracking, payments, custom modes, Team Bot logins and sharing, connector requests in Slack and contacts in the Vault. HeyGen, meanwhile, says its voice model is what lets Grok Bot make phone calls that sound like you.
Data Bot answers a question about Team Bots with a summary and charts.Data Bot עונה על שאלה על בוטי צוות, עם סיכום וגרפים.Image: תמונה: @bot on X
A New Test Where Even the Best Model Scores Twelve Per Cent
SemiAnalysis launches GDPx for valuable agent work; Claude Opus 5.5 leads, Gemini 4 Carbon wins on price
By Our Correspondent with the Stopwatch
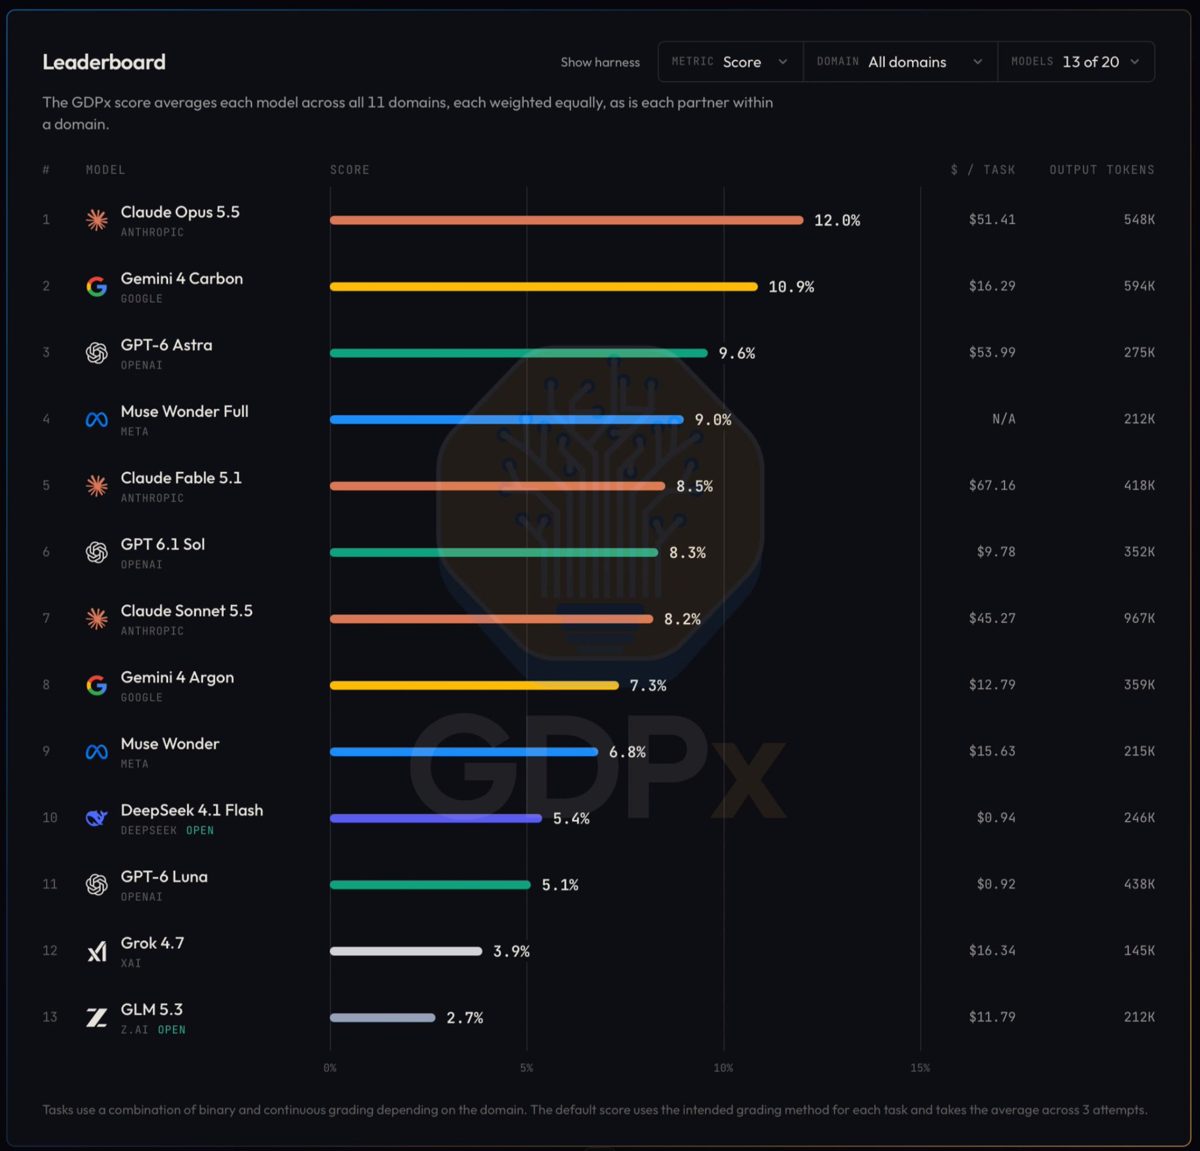
SemiAnalysis released GDPx, a benchmark of agent tasks across 11 of the most valuable work domains. It is hard on purpose: the leader, Claude Opus 5.5, scores 12.0 per cent, ahead of Gemini 4 Carbon at 10.9 and GPT-6 Astra at 9.6. Grok 4.7 scores 3.9.
Cost tells a second story. Opus spends $51.41 per task, Carbon $16.29, and DeepSeek V4.1 Flash reaches 5.4 per cent for 94 cents. Sundar Pichai welcomed a benchmark “with headroom” and pointed at Carbon’s cost line.
Artificial Analysis added a money measure of its own: daily GPU rental prices from Silicon Data now feed a “throughput per dollar an hour” score in its data-centre benchmark. Among rentable systems, Nvidia’s B300 generally leads.
The GDPx leaderboard, with each model’s cost per task on the right.טבלת GDPx, עם עלות המשימה של כל מודל בצד ימין.Image: תמונה: @SemiAnalysis_ on X
The biggest character shift Artificial Analysis has measured: tidier, colder, and fond of tables
By Our Correspondent on the Couch
On AA-PersonalityBench, Moonshot’s Kimi K3.1 Pro moved an average of 30 percentile points across 30 traits compared with Kimi K3, the largest change from a direct predecessor the benchmark has seen. The next biggest, 23 points, was GPT-6 Sol to GPT-6.1 Sol.
Organisation jumped from 33 to 88, while warmth fell from 93 to 51, imagination from 88 to 53 and expressiveness from 93 to 63. The new Kimi writes with fewer em dashes, asides and italics, and more bold text, headings and tables. Its closest relatives are now GPT-6.1 Sol and GPT-6 Astra.
A separate update to the AgentTime benchmark, which checks whether models keep track of time, estimate how long work will take and look back on it, found GPT models clearly ahead, especially the GPT-6 family.
Dory1-4B reruns its middle layers for a better score, and Mistral Large 4 breaks a molecule on screen
By Our Correspondent in the Loop
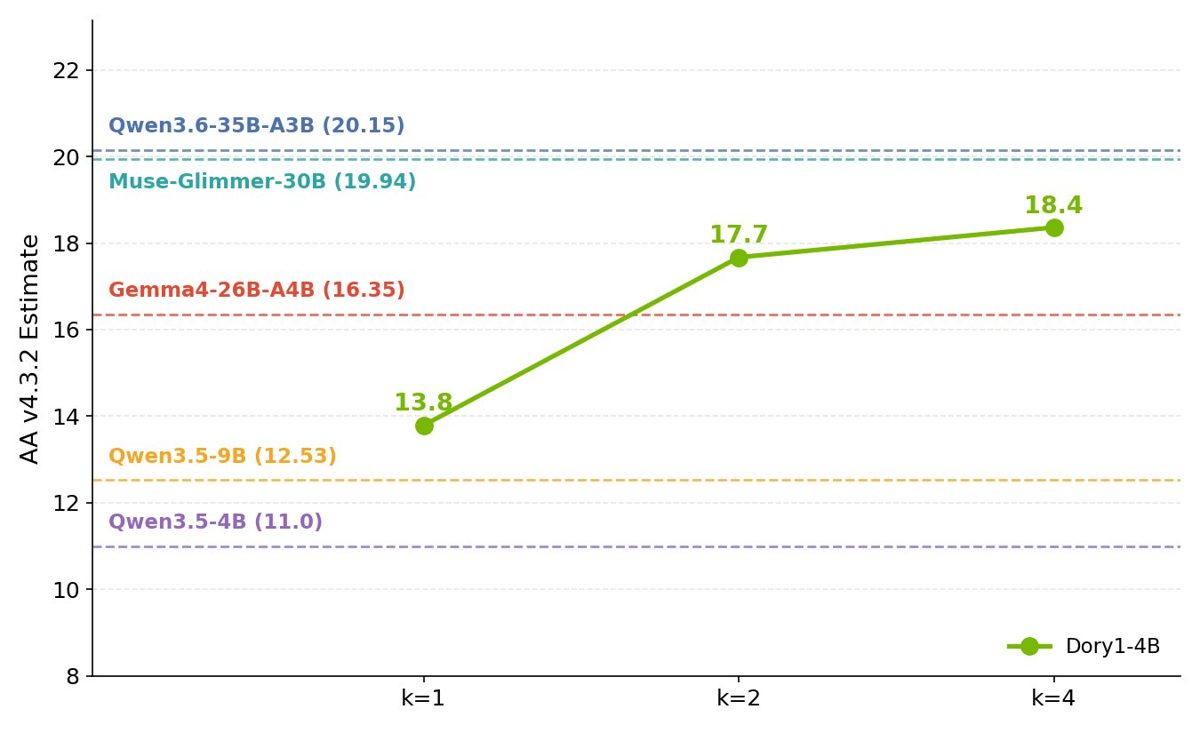
Nvidia released Dory1-4B, a “looped” language model with 36 layers: eight input layers, a block of 20 that can run once, twice or four times, and eight output layers. Running the block more often lifts its estimated Artificial Analysis score from 13.8 to 17.7 and then 18.4, above Gemma 4 26B-A4B at 16.35.
Mistral showed off its new flagship. Given a short prompt, Mistral Large 4 wrote a quantum-chemistry solver from scratch, chose for itself how to break the molecule, built a 3D view with a slider, and checked its energies against the PySCF library to an accuracy of 1e-13.
More loops, higher score: Dory1-4B at one, two and four passes.יותר לולאות, ציון גבוה יותר: Dory1-4B במעבר אחד, שניים וארבעה.Image: תמונה: @scaling01 on X
OpenAI Pays Hackers More, Your Dot Gets New Brains, and Hermes Comes Knocking
Short items from the rest of the feed
By Our Roving Correspondent
OpenAI more than quadrupled bug-bounty rewards for critical findings, up to $172,000 with bonuses, and says it will top up awards from the past 30 days. It is also planning an internal security sprint with Cathedral Systems, whose researchers will attack its defences using OpenAI’s own models. Separately, it introduced LifeVal, a benchmark built from what thousands of ChatGPT users want help with, from childcare to government services and personal finances.
Thibault Sottiaux says ChatGPT’s dots will soon run on more models, including GPT-6 Astra and GPT-6.1 Terra, and pick the right one for each part of a task. DeepSeek Harness added Creator Mode, which turns ideas into plugins. Runway arrived as a Cursor plugin.
After Elon Musk wrote that the cost of serving Grok Bot had been “unsustainably high relative to revenue”, Nous Research answered with a one-liner: “hermes migrate grok-bot”, a command in its open-source Hermes agent. And @poteto’s browser game, made with Grok Bot and Cursor, passed almost 100,000 plays.
Wren & Robin read you this morning's dispatches, with banter.
Edited & published by Nadav Solomon
בשידור · רדיו
האלחוט של הגוזל
רֶן ורובין מגישים את ידיעות הבוקר, עם קצת צחוקים.
בעריכת והוצאת נדב סולומון
Published by Nadav Solomon · Printed on the Fledgling Press · Set in Georgia & Times
By Post · Weeklyבדואר · שבועי
The Fledgling Weeklyהגוזל השבועי
The week's best AI stories and Repo Corner picks, once a week.מיטב ידיעות ה-AI של השבוע ובחירות פינת הריפו, פעם בשבוע.
Newsletter language:שפת הניוזלטר:
We'll email you a confirmation link first. Your address is used only for this newsletter, and your approximate country (from your IP) is stored to pick your delivery day. Never shared; every issue has a one-click unsubscribe.קודם נשלח לך קישור לאישור. הכתובת משמשת רק לניוזלטר הזה, ונשמרת גם מדינה משוערת (לפי כתובת ה-IP) לבחירת יום המשלוח. לא מועבר לאף אחד, ובכל גיליון יש הסרה בלחיצה אחת.
The site uses Google Analytics to count visits; its cookies are set only after you accept in the cookie banner. Privacy policy.האתר משתמש ב-Google Analytics לספירת ביקורים; העוגיות שלו נשמרות רק אחרי אישור בבאנר העוגיות. מדיניות פרטיות.